Jeff Rivett has worked with and written about computers since the early 1980s. His first computer was an Apple II+, built by his father and heavily customized. Jeff's writing appeared in Computist Magazine in the 1980s, and he created and sold a game utility (Ultimaker 2, reviewed in the December 1983 Washington Apple Pi Journal) to international markets during the same period. Proceeds from writing, software sales, and contract programming gigs paid his way through university, earning him a Bachelor of Science (Computer Science) degree at UWO. Jeff went on to work as a programmer, sysadmin, and manager in various industries. There's more on the About page, and on the Jeff Rivett Consulting site.

All posts by jrivett


Bingbot being used to attack web sites

Someone has apparently figured out how to use Microsoft’s search engine to send garbage traffic to targeted web sites. In recent weeks, one of my client sites has been subjected to a steady stream of worthless traffic from a range of IP addresses owned by Microsoft and used by its search crawler, bingbot.

Here’s a request from bingbot that was received at the exact same moment as three similar requests recently:

13.71.172.235 - - [30/Sep/2026:12:17:16 +0000] "GET /catalogsearch/result/index/?caliber=145&dir=asc&order=price&p=2&q=C%3A%5CUsers%5CLENOVO%5CDesktop%5CAll+translations%5C2-+Translations%5CReceipts%2C+Invoices%2C+Bills%2C+etc%5C2023%5C9-+September+till+December+2023%5CReceipt+No.+1836+-++Phoenicia+Station+-+Baabda+-+24+October+2023%5CEnglish+-+Receipt+No.+1836+-++Phoenicia+Station+-+Baabda+-+24+October+2023.pdf HTTP/1.1" 403 494 "-" "Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; bingbot/2.0; +http://www.bing.com/bingbot.htm) Chrome/116.0.1938.76 Safari/537.36"

Astute readers will notice that this request was rejected by the target web site (the HTTP response status code is 403 – Forbidden). That’s because the site is actively blocking all the IP addresses used by bingbot. Well, the ones I know about anyway. You can also see that the host sending the request identifies itself as ‘bingbot/2.0’.

To confirm that these requests are in fact coming from legitimate bingbot hosts, I looked up the source IP address (along with many others), and found that 13.71.172.235 is one IP in the range (CIDR) 13.64.0.0/11, which is owned by Microsoft Corporation. It’s part of a Microsoft Azure Cloud data center in Toronto, Canada, within the Microsoft domain msn.com.

There’s also a tool on the Bing Webmaster Tools site that checks whether an IP address is part of bingbot. I used it to confirm that 13.71.172.235 is indeed bingbot.

The first part of the request is GET /catalogsearch/result/index. This is the type of request that is logged when a (human) user performs a search using the site’s own search function. The other three requests (received at the exact same time) were also search requests, using different search terms.

There are several reasons why these requests make no sense:

  • The search terms are unrelated to the subject of the web site being searched.
  • A human site user would not (and could not) send multiple search requests at the exact same moment, especially without related requests before and after each search request.
  • There is no way that the information returned by the web server in response to these requests is of any use to bingbot or any other search engine.
  • The primary function of search bots like bingbot is to collect information from web sites, which is done by reading a site’s home page, making a list of links to other pages on the site found on the home page, then visiting those other pages and processing them the same way. That’s the simplified version of what they do; search bots also read sitemaps to find pages to index. But the requests we’re seeing from bingbot are for pages that do not appear anywhere on the site or in its sitemap.
  • Search engines are supposed to read and follow the instructions in the special site file called ‘robots.txt’. For the site in question, there are directives in robots.txt that specifically disallow ‘catalogsearch’ requests by all bots. Bingbot is clearly ignoring those directives.
  • In my attempts to mitigate this problem, I added a directive to robots.txt that disallows all access by bingbot. That directive was also ignored by bingbot, which left me with no choice but to block bingbot hosts completely.
  • The search request is looking for a PDF file on a specific path. The web site in question does not serve any PDF files, and certainly not from a local Windows folder.

Unfortunately, search requests like the one above tend to use more server resources than ordinary requests, such as a request to view a single product page. When several complex search requests are made at the exact same moment, they can have a significant (negative) effect on site performance. When that happens every few minutes, all day, every day, the cumulative effect can cause the site to become unresponsive. That is the definition of a Denial of Service (DoS) attack. When the requests come from multiple IP addresses, that’s a Distributed Denial of Service (DDoS) attack.

The good news is that since the requests are all coming from bingbot hosts, it’s easy to spot and block them. Many DDoS attacks come from unrelated hosts, and don’t identify themselves as anything other than ordinary web users, which makes them more difficult to categorize and block.

Here’s another one of the four requests received at the same time as the one above:

13.71.172.235 - - [30/Sep/2026:12:17:16 +0000] "GET /catalogsearch/result/index/?action=152&ammotype=194&cat=62&condition=568&q=most+workshop+1+%E0%B8%95%E0%B8%B1%E0%B8%A7%E0%B8%AD%E0%B8%A2%E0%B9%88%E0%B8%B2%E0%B8%87%E0%B8%81%E0%B8%B2%E0%B8%A3%E0%B8%A7%E0%B8%B4%E0%B9%80%E0%B8%84%E0%B8%A3%E0%B8%B2%E0%B8%B0%E0%B8%AB%E0%B9%8C%E0%B9%81%E0%B8%A5%E0%B8%B0%E0%B8%AD%E0%B8%AD%E0%B8%81%E0%B9%81%E0%B8%9A%E0%B8%9A%E0%B8%AD%E0%B8%B2%E0%B8%84%E0%B8%B2%E0%B8%A3%E0%B8%9E%E0%B8%B1%E0%B8%81%E0%B8%AD%E0%B8%B2%E0%B8%A8%E0%B8%B1%E0%B8%A2+5+%E0%B8%8A%E0%B8%B1%E0%B9%89%E0%B8%99&sale_status=1142 HTTP/1.1" 403 494 "-" "Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; bingbot/2.0; +http://www.bing.com/bingbot.htm) Chrome/116.0.1938.76 Safari/537.36"

As you can see, the query text includes a long string of encoded characters. When decoded, the string is “ตัวอย่างการวิเคราะห์และออกแบบอาคารพักอาศัย 5 ชั้น”. Those non-English characters are Thai, and translate to “Example of the analysis and design of a 5-story residential building.” The web site in question is in English only, and the translated search string is completely unrelated to the subject of the site.

Currently, these pointless requests from bingbot hosts comprise about one quarter of all traffic hitting the site. About one request in 20 looks like it might be legitimate bingbot crawling activity. Most are like the ones above.

I did reach out to Microsoft/Bing support about this, but they don’t seem very interested in solving the actual problem, and instead are insisting that I unblock bingbot so that it can read the crawling instructions specific to bingbot in the site’s robots.txt file. They’ve asked me to add a crawl-delay directive to robots.txt, which — if bingbot paid attention to it — should reduce the number of requests coming from bingbot. But even if that worked, it would not address the actual problem.

I can’t justify opening up the site to this traffic just to jump through a pointless hoop. Luckily, very few people actually use Bing search, so blocking bingbot is unlikely to have much effect on the amount of legitimate traffic coming to the site.

In my opinion, there are two possible explanations for this bizarre bingbot traffic. The first is that there are serious bugs in bingbot or in its configuration. That seems unlikely. The second is that someone has found a way to hijack publicly-available tools provided by Microsoft to send the traffic.

The Bing Webmaster Tools page includes a tool for checking a URL. Previously, any URL could be entered. At some point, Microsoft changed this tool so that only URLs for web sites owned by the user can be checked. So it seems unlikely that this is the method being used. Of course it’s also possible that the perpetrators have found a workaround for this limitation.

Only time will tell whether Microsoft will take this problem seriously, determine what flaw is allowing these requests, and fix the flaw. In the meantime, although the requests continue, they are blocked and logged, and have little effect on the site.

Like many people, I was a huge fan of Google when its search service first became available. Before Google, web searching was frustrating and perilous. I’ve gradually become less of a Google fan over the years, but at least their search bots respect robots.txt, and don’t incessantly crawl nonexistent URLs with nonsensical search terms.
AI site scraper bots are overwhelming many web sites

In the never-ending search for content to feed into their Large Language Models, ‘AI’ companies are using distributed networks of bots (automated programs) to download the contents of web sites everywhere on the Internet. Many sites are being overwhelmed by this traffic. Some site owners are being forced to upgrade their hosting service, while others have simply shut down.
If your response to that is to point out that Google does the exact same thing, and has for years, you’d be right, except for a few important differences:

  • Google’s searchbot doesn’t try to download every page on every web site. It’s much more selective about what it grabs.
  • Googlebot clearly identifies itself, which makes it much easier to classify its requests and limit its impact. The vast majority of ‘AI’ scraper bots falsely identify themselves as ordinary web users.
  • Google publishes a list of host IP ranges used by Googlebot, and they consist of specific, limited subnets that are clearly owned by Google. The vast majority of ‘AI’ scraper bots are spread around the world, on largely unrelated groups of hosts, often running on virtual private servers owned by VPS providers.
  • When Googlebot crawls your site, one or two hosts read a small batch of related/linked pages, then go away and come back for more later. ‘AI’ crawlers spread their requests across hundreds or even thousands of hosts, each one reading as little as one page, which makes identifying and blocking them difficult.

All of these things make the job of managing traffic for a web site much more difficult than it was before the current ‘AI’ boom.

In my work on managing traffic for clients, I have been lucky in that two of them are not legally allowed to sell to anyone outside of Canada. For those clients, I eventually just blocked traffic from every country except Canada. Traffic from major search providers is always allowed, and special procedures are required for certificate updates, but this made a huge difference. Web sites that need traffic from other countries obviously can’t use this drastic approach.

Thankfully, all of this pointless and damaging traffic will stop when the current ‘AI’ bubble bursts, and that can’t come soon enough for me.

The Register talks about this, describing the new ‘AI’ crawlers as site destroyers, which is accurate.

Here’s Drew Curtis, the owner/operator of the long running humour site fark.com, talking about this problem.

The EFF posted about this problem and suggests some solutions.

There has been some progress on ‘local models’, which refers to running LLM ‘AI’ software locally (i.e. on your own computer). The idea is that if you can run an LLM on your own computer, you don’t have to pay for the use of commercial services. And local models do actually work, but with much less useful results. Your laptop just doesn’t have the processing power to produce truly useful results. According to Sean Goedecke, this is unlikely to change, even with significant increases in processing power. So the ability to run local models will not have any effect on the deluge of traffic hitting web sites.

Dear Microsoft: stop screwing with my computer

At one point, not many years ago, we had control over our own Windows computers. Microsoft has ripped that control from us gradually, and with Windows 11, not only does Microsoft decide which patches your computer needs, it also decides when to install them, and when to restart your computer to complete them.

Sure, there are ways to regain some control. Updates can be delayed, and restarts can be scheduled. But that’s only if you’re running the more expensive versions of Windows.

Various update-induced nightmares

Power settings reverted

Sometimes, after Microsoft installs updates, the Windows power settings revert to their out-of-the-box defaults: the display turns off after a few minutes, and the computer goes to sleep after a few additional minutes of inactivity. I’ve never found a satisfying explanation for why these settings revert.

I suppose it’s possible that Microsoft is trying to be a good citizen, and tell the billions of Windows computers it effectively manages to go to sleep when they are no being actively used.

Sure, that saves power. And sure, most of the time a sleeping computer is just slightly annoying to its user. And yes, the defaults make a lot of sense for laptops. But the Windows sleep feature isn’t exactly reliable. Most power users leave it permanently disabled because it just causes too many problems.

It’s also a huge problem for computers that are mainly used remotely. When a remote Windows PC goes to sleep, it becomes impossible to access remotely. Someone has to go to the computer physically and hit the keyboard to wake it up.

Sure, there’s technology to get around this, such as Wake-On-LAN. But I have yet to see WOL work reliably on any Windows computer where I’ve tried it.

Incidentally, this exact scenario recently happened to me (again), and there was no way to access the remote PC until the business reopened two days after I needed remote access.

Default apps revert to Windows defaults

This has happened on Windows computers I manage more times than I can remember. There’s no pattern to it. I would almost prefer if this happened after every update, because then I would know that I always have to reset them.

It’s no coincidence, I’m sure, that the defaults involve setting up Microsoft apps to open everything. Nothing to do with the fact that a lot of those defaults involve opening files in Edge, and the fact that Edge is basically hated by everyone and used very little, at least intentionally.

Worse still, Microsoft has made it increasingly difficult to change these settings. The latest user interface is awful. And it’s now effectively impossible for an application to make itself the default for specific file types. Apps typically now have a message apologizing for not being able to make those changes, and telling the user that they have no choice but to use the crappy Windows interface.

Resetting all the default apps on my Windows 11 computer takes about an hour. I’ve spent a lot of time testing applications, and have settled on a collection that works very well for me. Very few of them are Microsoft apps. I have to keep notes about it, because I can’t remember all of the details.

Updates and reboots interrupt critical processes

You’ve probably heard the stories about people giving important presentations, only to be interrupted by updates and reboots. It’s even happened to Microsoft executives.

Microsoft has tried to improve this, offering to only install updates and reboot after hours, but those settings are far too limited.

Updates are not properly tested

Those other problems are annoying and problematic, but they pale in comparison with those times when Microsoft’s Windows update ineptitude has caused major outages around the world. There have been estimates about how much these problems have actually cost in terms of lost productivity, and the numbers are significant.

Of course, every time this happens, Microsoft says it was impossible to predict, and that it will never happen again. Here’s a suggestion, Microsoft: try testing updates properly before foisting them on millions of innocents users.

Conclusion

So hey, Microsoft. Kindly fuck all the way off with this bullshit. Linux looks better all the time.

Generative AI tools: enjoy them while you can

I’ve enjoyed playing around with generative AI tools like ChatGPT and the new, generative features of image editors. I used ChatGPT to generate most of the definitions on this site (which I carefully reviewed and approved before posting). I even tried a code generator, though the code proved unusable.
But there’s a problem with all these technologies: they’re expensive. It takes a lot of processing power to run these tools. You don’t notice this, because when you ask MS Paint to generate an image, your computer’s fans don’t even speed up. That’s because the real work is always done on a remote computer, or multiple computers, owned by an AI company or some other large company that’s bought into the current AI craze.

Okay, so what? As long as I don’t have to pay for it, why should I care how much processing power is required? First of all, the companies that are are paying for all that work are currently subsidizing it; they are betting enormous amounts of money that these tools are here to stay. Some of them are charging users for their services, but so far none of them are making anywhere near what they’re spending. That’s not sustainable, and eventually they will need to either start recovering their costs, or discontinue their services.

We are starting to see advertising in generative AI services, and while that may offset the costs of running an AI data center to some degree, I doubt ads will come close to paying for all of that infrastructure and energy.

The second problem is that the processing power required by generative AI uses a lot of energy. Like, huge amounts of energy. You don’t see that, but it’s one reason generative AI services are so expensive to operate. Big companies are building huge new data centers just to host generative AI services. And they’re using incredibly large amounts of energy to power them. That’s not going to change, and at some point, government and industry regulators are going to start making noise about it. When an industry uses a lot of energy, regulators uses various methods to curb the excess, including taxes. I predict that governments will start taxing AI companies, which will make generative AI even more expensive.

So again, at some point, companies providing generative AI services will have to recover their ever-increasing costs. There are a few ways to do that, but the most obvious one is to start charging for those services, or to start charging a lot more. That will kill demand for those services, and eventually only organizations with very deep pockets will be able to afford them. At that point, the generative AI bubble will burst, and will fade into the background, just another tech fad that amused us for a while.

The other major issue with generative AI is legality. All generative AI uses existing media, much of which is obtained from public sources. The legal fights about this have only just started, and will only get worse as service providers start trying to make money from what is basically the work of other people. It will be interesting to watch as an outsider, and will keep copyright lawyers working for years.

NVIDIA

NVIDIA manufactures the processing chips that power generative AI. At this point I think the smart move would be to start short-selling NVIDIA stock, the value of which is currently skyrocketing, based on an assumption that generative AI is here to stay. When the NVIDIA stock tanks after this AI craze, anyone brave enough to short it will make enormous amounts of money.

Conclusions

Of course, it’s always possible that there will be a breakthrough in processing power, or the associated power requirements, and if that happens soon enough, my predictions could end up being way off. But it would need to be a big breakthrough, and that doesn’t seem likely.

So, enjoy these interesting AI tools while they last. Just don’t count on being able to afford using them in a few years. If you’re a writer, artist, or programmer who depends on generative AI tools for your livelihood, you are heading for trouble.

UPDATE 2026Mar06: here’s a fascinating ‘interview’ with the Claude chatbot, in which the human interviewer asks a series of questions about the financial realities of Nvidia’s stock price, and the viability of AI-powered services. Claude is not optimistic.

UPDATE 2026Apr22: Kyle Kingsbury recently published a lengthy analysis of what’s going on with LLMs and related technologies, and it’s a doozy. Highly recommended. The Future of Everything is Lies, I Guess (Bullshit About Bullshit Machines).

Reminder: view email as plain text

Security professionals have been saying it for years. The specific dangers associated with email have changed during that time, but the advice remains valid, and applies to everyone who uses email.
While styled text in emails looks nice, and can increase readability, those benefits are massively outweighed by the associated risks.

I’ve been viewing all incoming email as plain text since I worked at the help desk of a major Canadian university. I saw first hand the damage that could be done with malicious email.

This morning, I received a phishing email that once again reinforced this old, but solid advice.

The Phish

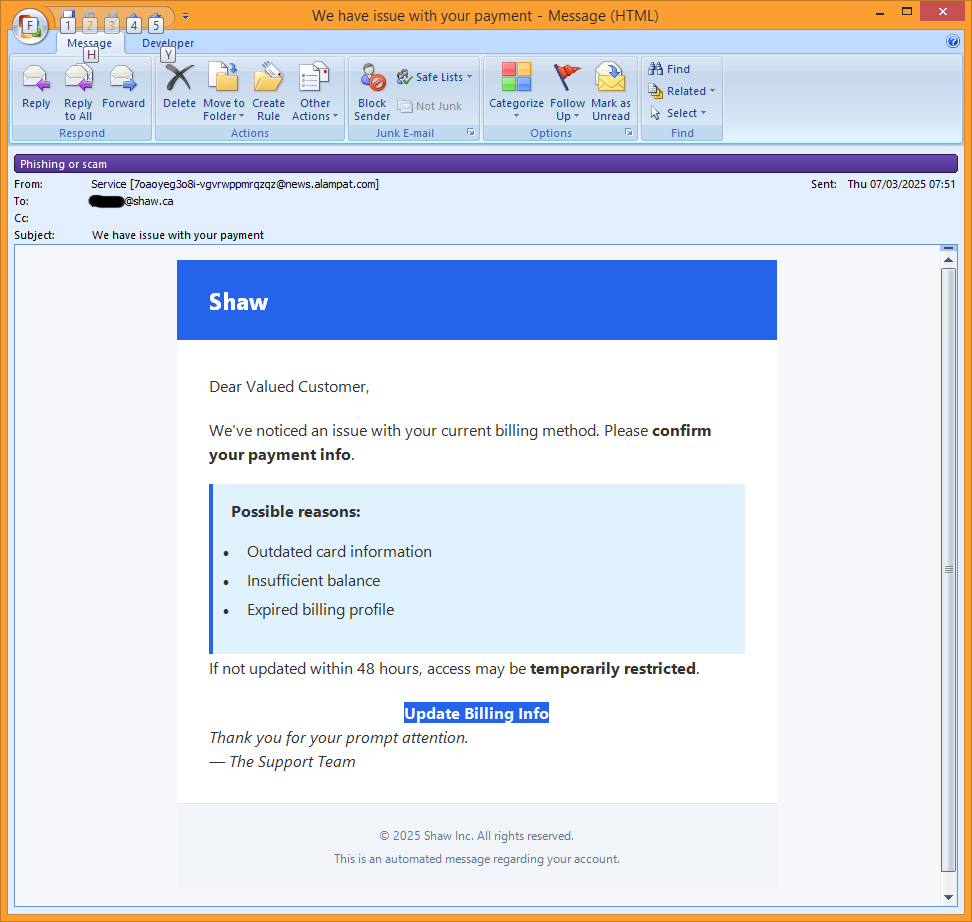
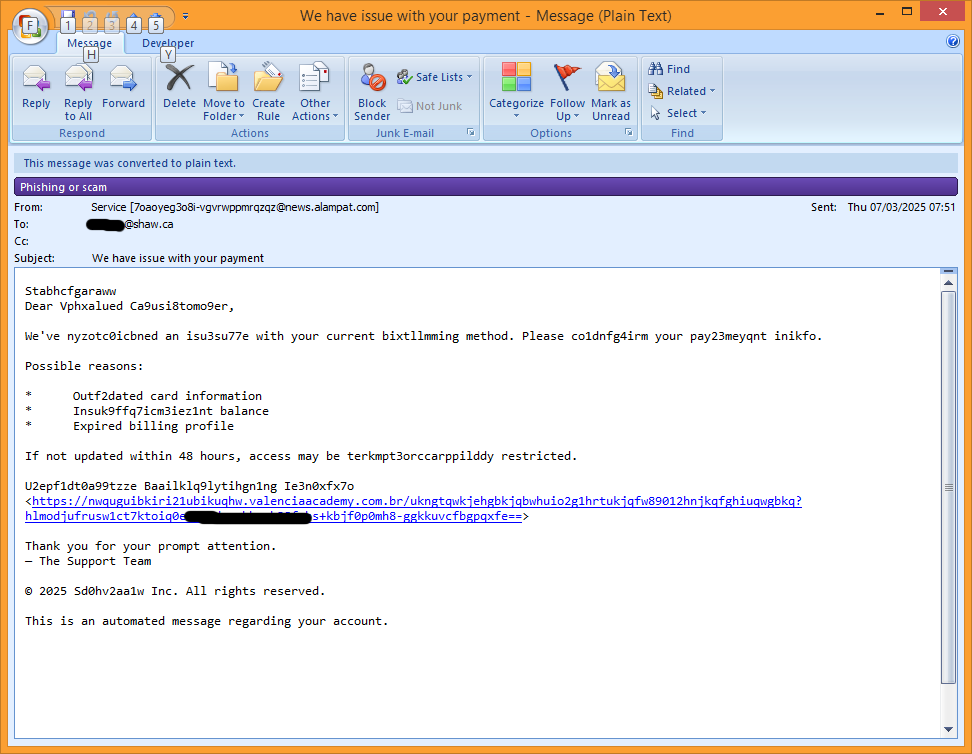
Here’s what the email looks like when viewed in HTML mode, which renders underlying code as styled, formatted text:

The phishing email, rendered in HTML mode by Outlook.

Looks legitimate, at first glance. Upon closer inspection, the ‘From’ address is clearly unrelated to the supposed sender. It’s a long, randomly-generated string of characters, followed by ‘@news.alampat.com’. The long string of random characters may be designed to push the sender’s domain (news.alampat.com) off the screen on some devices. The domain itself doesn’t even exist.

Other than that, nothing suspicious stands out.

Savvy email users also know that you can usually hover the mouse pointer over a button or link, to show the web address hidden behind it. Doing that for this email reveals that clicking the ‘Update Billing Info’ button will send your web browser to: randomtext.valenciaacademy.com.br/randomtext?randomtext-randomtext==

Analysis of the actual address using the amazingly useful site scanner at urlscan.io shows a fake Shaw webmail login page, which looks identical to the actual Shaw webmail login page.

If you clicked the button in the phishing email, you would arrive at this legitimate-looking login screen. If you then entered your Shaw email username and password, the phish would be successful: the perpetrators would have the login ID and password for your email account. Your account could then be used for anything, up to and including identity theft.

Now, here’s what I saw when I opened the same email, which again, I see as plain text because I’ve configured Outlook that way:

The plain text version of the email. Obviously phishy.

It’s immediately obvious that many important words in the email have been partially obfuscated by inserting garbage characters. These characters are hidden in the HTML view. The web address associated with the ‘Update Billing Info’ button is also shown clearly. And that’s the problem, or rather one of the problems, with viewing email in rendered HTML mode: information is hidden from your view.

If you don’t mind the idea that the email you open includes hidden — and potentially very dangerous — information, I guess you can keep running that risk. But I cannot recommend it.

Take a few minutes to look at your email application’s settings. It should have an option to display all email as plain text. Enable that to improve your email safety.

Microsoft update adventures

Yesterday I fired up my media PC, booting to Windows 10, to watch some episodic visual media (you know, TV shows) that we refer to as ‘comfort food’ around here.

Imagine my surprise when instead I saw a series of weird dialog boxes pop up on the screen, many of which were blank. Was it some kind of malware? Nope, it was Microsoft Copilot, trying to install itself and going berserk.

I tried following the prompts I was able to see, but those just led to more dialogs, including prompts for a PIN code that I don’t normally use when logging in. On that computer, I had previously given in to Microsoft’s increasingly strident demands that I use a Microsoft account to log in. So the PIN prompt was confusing.

I wish I had taken video of the whole thing. It was both comical and horrifying. My roommate looked on while I tried in vain to close blank dialogs that kept recreating themselves.

Eventually I recognized the Copilot logo on the taskbar for some of these dialogs, and caught enough of one briefly-flashed message to realize that this was Copilot, apparently attempting to install itself.

. . .

Windows 10 marked a major change in the way Microsoft updates the operating system: basically, updates are pushed to your computer whether you want them or not. You can delay them, sort of, but you can never stop them completely.

I have serious misgivings about that, but also about Microsoft’s decision to push Copilot to PCs running a version of Windows that won’t even be supported in a few months. Windows 10 support will end in October of 2025.

. . .

Anyway, once I realized that the barf being spewed in my face by Microsoft was related to Copilot, something in which I have zero interest, I started killing tasks. The ensuing game of whac-a-mole went on for a few minutes before I finally won, and the insane dialogs stopped appearing.

I then proceeded to remove Copilot-related garbage from the Startups list, which I later confirmed did in fact stop this mess from occurring again at the next startup.

That was half an hour of my life that I will never get back. Thanks, Microsoft!

Luckily, I was only booting to Windows on my media PC temporarily, while working on a minor problem with Linux Mint on the same PC. I’ve now gone back to using Linux Mint, and I really hope I never have to boot to Windows 10 again.

. . .

Ever since Microsoft throttled back their own update testing, instead relying on problem reports from canaries (literally how Microsoft refers to people who opt in to receive Windows updates early), the number of problems resulting from updates has increased sharply (full disclosure: I only have anecdotal evidence of this).

Here’s another example of Microsoft update fun: a couple of weeks ago, Outlook stopped working on all PCs at a client’s location. After a lot of troubleshooting, it eventually became clear that a recent Microsoft update had hosed Office. The Office ‘repair’ function fixed most of the PCs, but on one, Office had to be reinstalled completely. Frustrating, annoying, and totally unnecessary.

Come on, Microsoft. You used to be just kind of shitty. Now it seems like you actively hate your users.

Is this the Google search page?

The folks at Microsoft are once again demonstrating their creativity in thinking up ways to trick people into using its web search service, Bing.
There’s an old joke about Internet Explorer that was never funny for Microsoft, because it was mostly true: that people only ever used the now-obsolete web browser to download the browser they want to actually use (Firefox, Chrome, etc.) When first installed, most versions of Windows configured Internet Explorer as the default browser. People who wanted to install a different browser were forced to use IE to download that other browser. Once that other browser was installed, the user would make it the default, and never see IE again.

Microsoft has been spanked for forcing their browser on Windows users, and as a result, their efforts along those lines are increasingly sneaky.

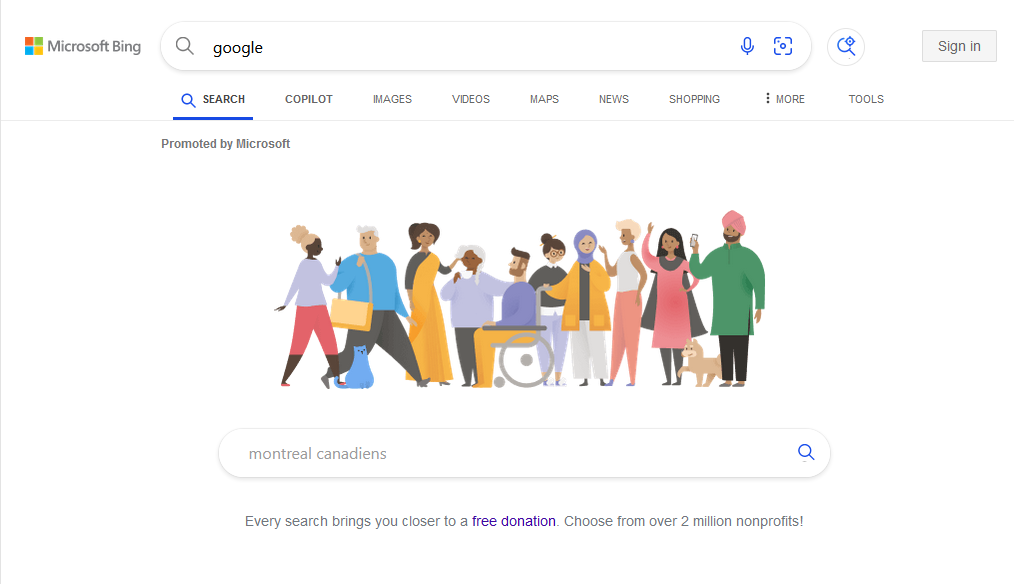
The most recent trick involves a special search results page that shows up in Bing (which is typically now the default browser for new Windows installs). When a user searches for ‘google’ in Bing, the results page has more than a passing resemblance to the default Google search page. Presumably Microsoft expects some people to assume they’ve found Google search and use the non-Google search page to perform subsequent searches. But of course they would still be using Bing.

Screen shot of Bing search results page for a 'google' search.
It does look like the Google search page, at first glance.

If you try searching for Google in Bing search, you’ll notice that the tricky results page automatically scrolls down a few lines, which effectively hides the Microsoft Bing header at the top of the page, and makes the trickery more difficult to spot. That also confirms that this is intentional. You can see the hidden content by scrolling back to the top of the page.

Screen shot of Bing search results page showing Microsoft header.
Scrolling up shows the Microsoft and Bing header info.

Microsoft is dancing right up to the edge of the danger zone here, and I admit to being somewhat impressed by this latest trick. They’re not actually pretending to be Google search, which would clearly be a problem. They’ve just done enough visually to make a user think that they’re using Google search, when in fact it’s anything but.

The fact that search alternatives like Bing and DuckDuckGo exist belies the notion that Google has an actual search monopoly. But Google’s dominance is so large, that it must be very frustrating to Microsoft. In a way I don’t mind these tricks, because tiny upstart Microsoft is just doing what they can to compete. But in the end, I have to officially take exception, because no user interface should ever be made to fool the user, unless of course we’re talking about an actual game.

Please do carry on with these shenanigans, Microsoft. They are very entertaining, and they give us something amusing to write about.

UPDATE 2025Jan15: And just like that, Microsoft removed the fake Google Search page from ‘google’ Bing search results pages.

Crowdstrike update kills millions of Windows computers worldwide

If you don’t have Crowdstrike security software on your Windows 10+ computers, you’re one of the lucky ones, along with folks running Linux or macOS.

If you do run Crowdstrike on Windows, this is a bad day, because manual, in-person intervention is the only way to get past the infinitely-looping Blue Screen Of Death affecting millions of computers this morning.

Of course, even if you’ve managed to avoid Crowdstrike on Windows, you’re likely to be affected by this bug, because there’s a good chance that services you use are going to be dealing with it today, and in the meantime will be unusable. That includes 911 call systems, airlines, healthcare providers, and banks.

What happened?

In the early hours of July 19, Crowdstrike pushed out an update for its security software. Crowdstrike client software on millions of computers dutifully applied the update, and the nightmare began.

Microsoft’s advice is apparently to try rebooting affected computers… up to 15 times. Apparently, eventually Windows figures out something is wrong and reverts the problematic update. Or possibly Windows runs long enough to download and install the fixed update from Crowdstrike. I don’t know if this is serious advice or not.

IT folks who manage hundreds or even thousands of affected computers are going to have a very bad day. It will be even worse if those computers are using full disk encryption. Some people are opting to recover from backups, but that gets tricky when encryption is used.

The part that really bugs me about this mess is that Crowdstrike staff clearly did not test the problematic update at all before pushing it out. If they had tested it even once, the problem would have been revealed.

Crowdstrike’s stock is apparently tumbling today, and I’m okay with that, because it will provide ample motivation for the company to improve its testing process.

In the meantime, it might be a good idea to take the next few days off, cancel travel plans, and pick up a good book. Unless you’re an IT person, in which case you’re going to be very busy today.

More about this from The Verge.

Brian Krebs reports on the problem.

Followup analysis from The Verge.

A new recovery tool from Microsoft can help with remediation efforts.

Crowdstrike’s Remediation and Guidance Hub.

Google Search ‘Classic’

You may have noticed that Google Search results are getting crappier. The ads are still fairly unobtrusive, but a typical search results page is filled with other junk that is often of no interest at all.

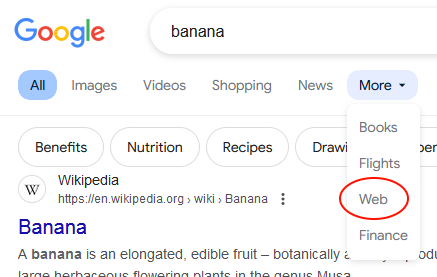
The good news is that Google just enabled a new feature in Search that may remind you of the good old days when search results were less cluttered. It’s called ‘Web search’. No kidding.

Google's new web search feature

To see Web search in action, go to google.com and search for something. Near the top of the search results page, you should see a horizontal menu, starting with ‘All’, ‘Images’, and ‘Videos’. Click the ‘More’ entry, and select ‘Web’.

As you can see, this cleans up the results page significantly.

I like this feature so much that I’ve made it my default search in Firefox. Here’s how to do that:

  1. By default, you can’t add custom search engines to Firefox. To enable that function, enter about:config in Firefox’s address bar and press Enter. You’ll be asked if you’re sure you want to proceed; click ‘Accept the risk’. Then type browser.urlbar.update2.engineAliasRefresh. You should see a small ‘+’ box to the right. Click that.
  2. Click Firefox’s ‘hamburger’ menu button, which looks like three horizontal lines, at the top right. Select ‘Settings’.
  3. Click ‘Search’ in the left sidebar.
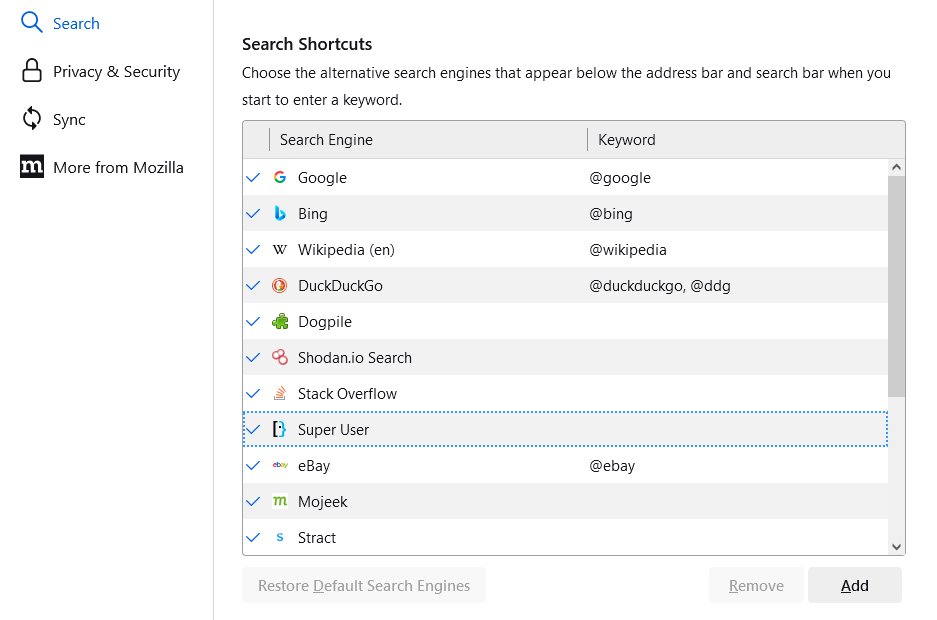
  4. Firefox search settings

  5. Scroll down to the ‘Search Shortcuts’ list. At the botton of that list, there should be an ‘Add’ button. Click that.
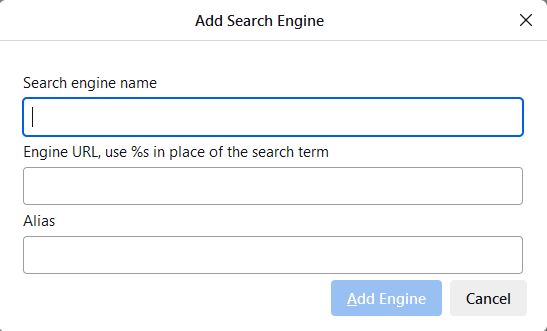
  6. Firefox Add Search dialogIn the small dialog that appears, enter a name for the new search (I call it ‘Google Classic’), the URL https://www.google.com/search?q=%s&udm=14, and then give it a shortcut alias like ‘gc’. Then click ‘Add Engine’.
  7. Scroll up the Settings page until you see ‘Default Search Engine’. Click the drop-down list and select the search engine you just added.

After making these changes, searches you perform in Firefox (by entering search terms in the address bar or search box) should produce ‘Web’ search results.

How good is your password?

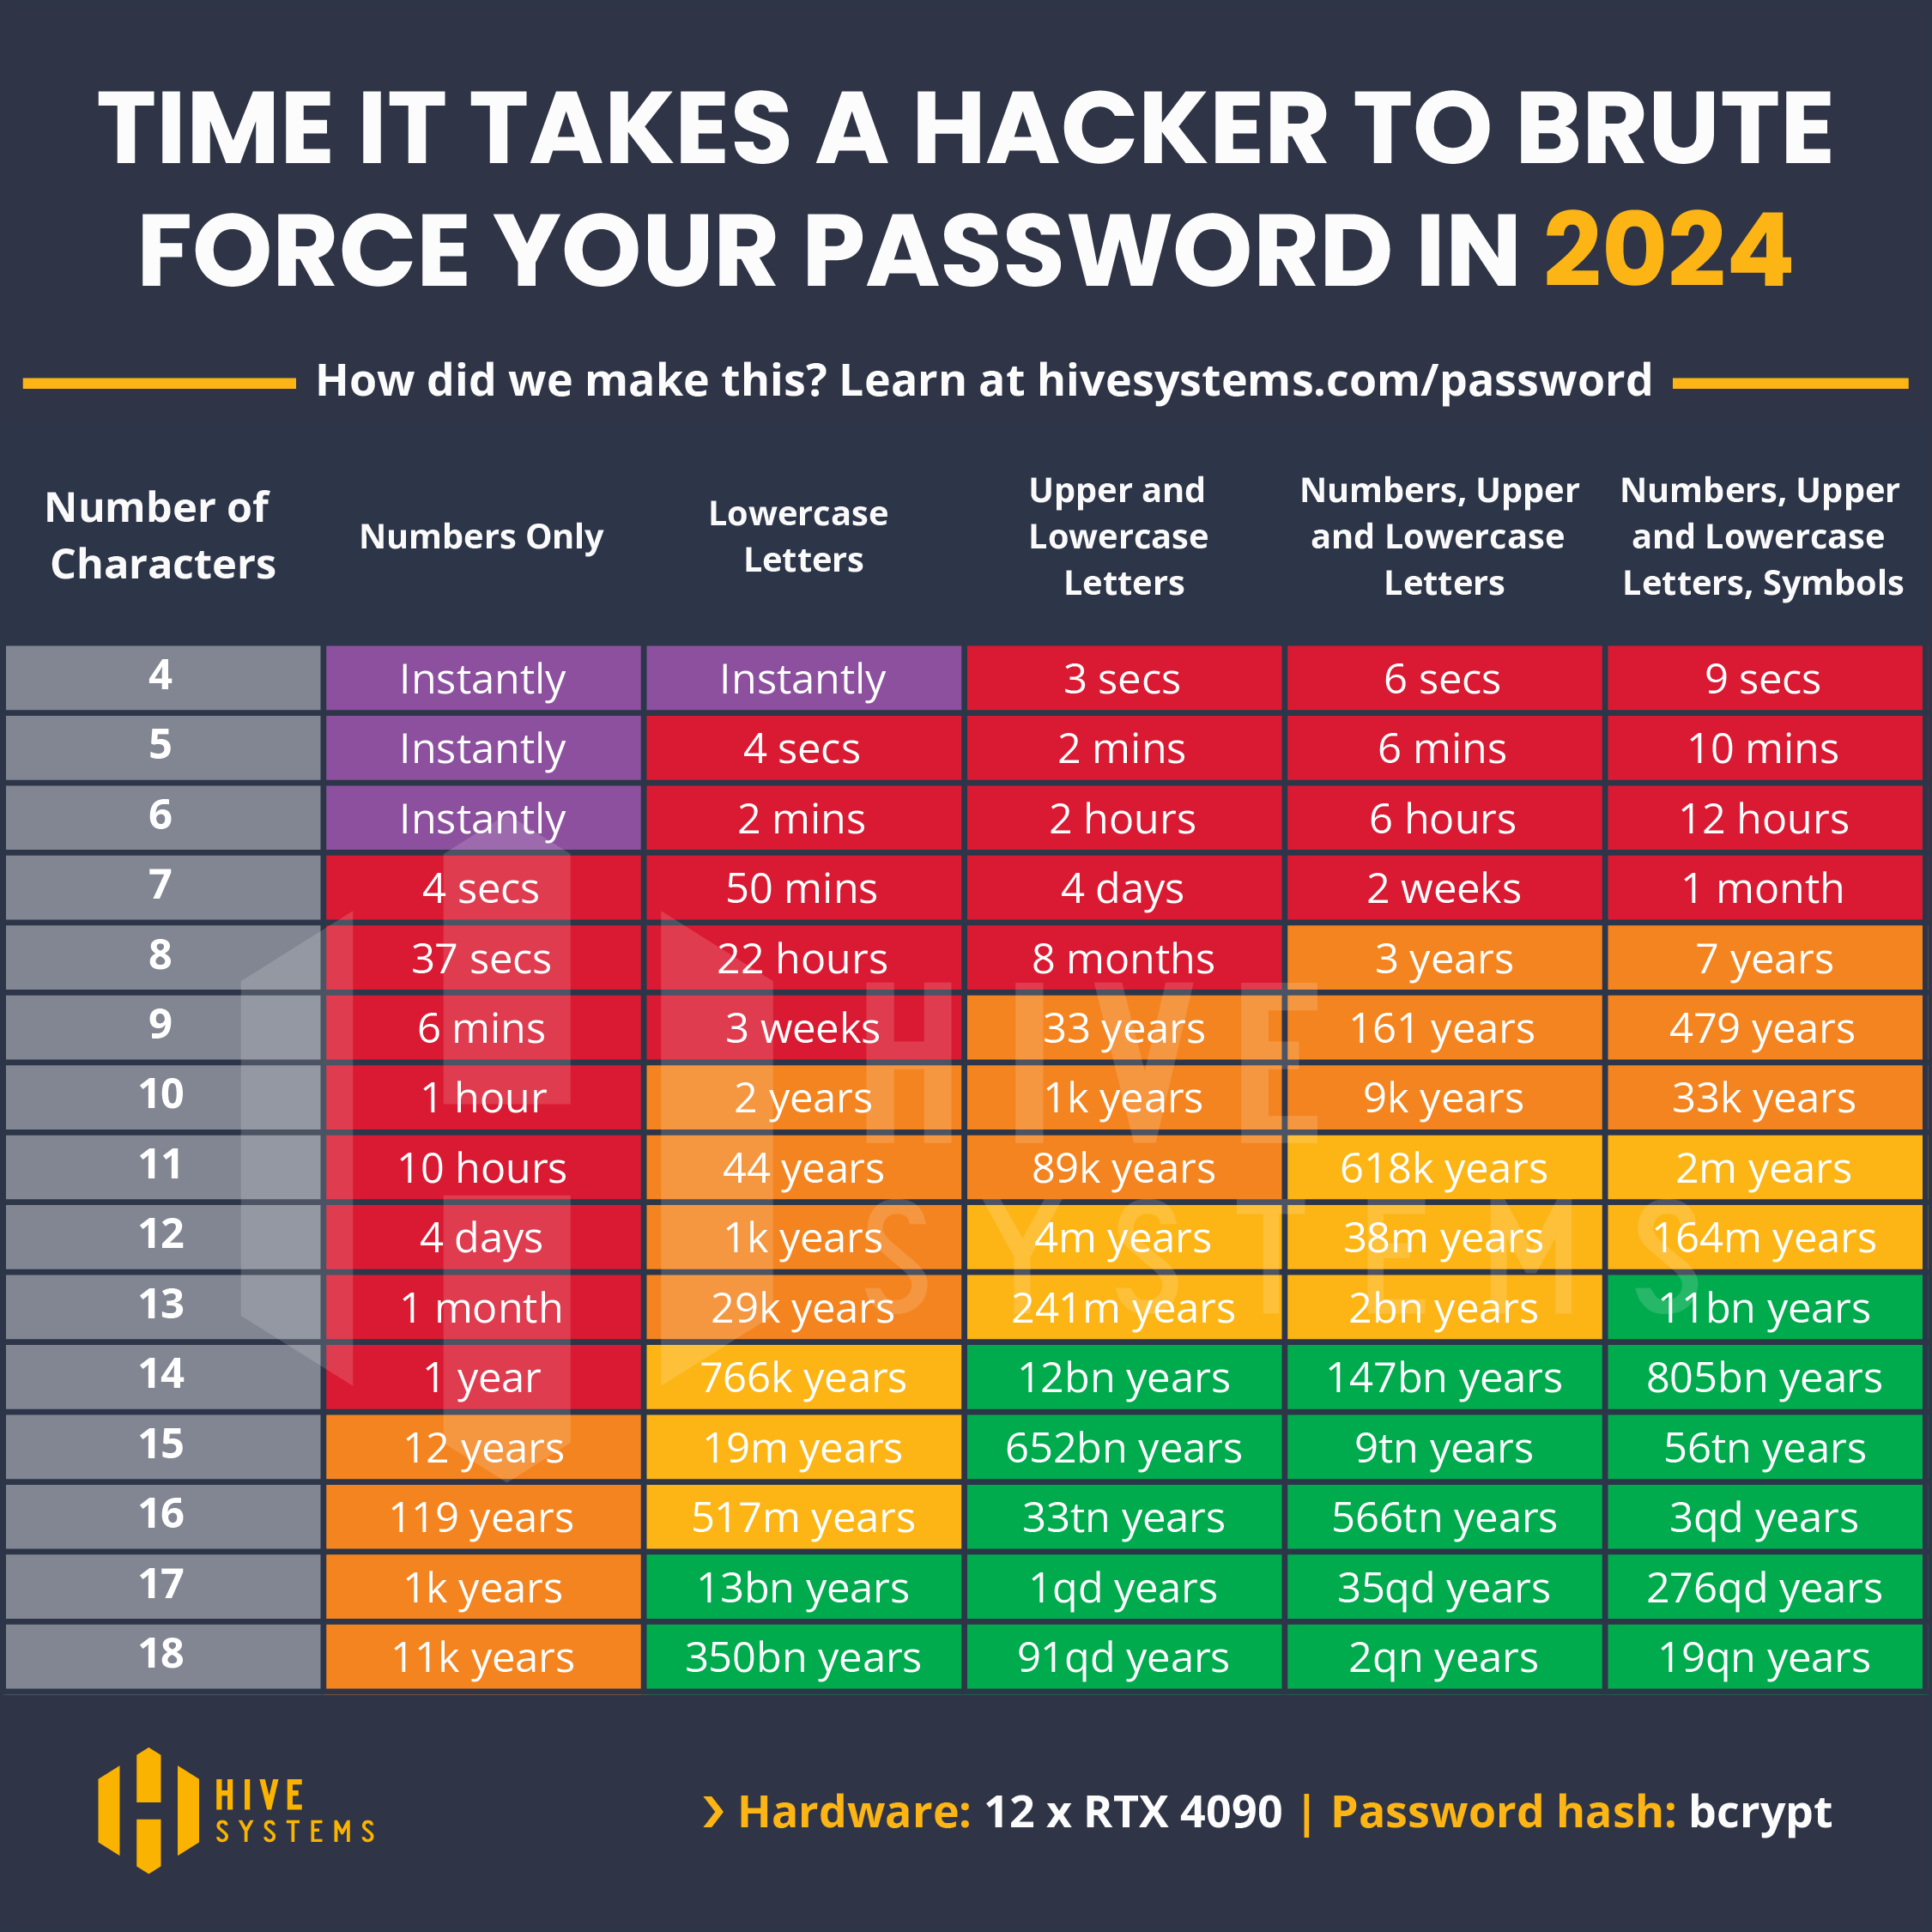
There’s a new chart from Hive Systems that you can use to determine how resistant your password is to brute-force cracking.

Password strength chart

Keep in mind that this is a moving target. As processor power increases and new technology arrives, brute-force attacks get faster. So if you have a similar chart published a couple of years ago, it’s likely already out of date. That’s why they included the year at the top of the chart.

It’s easy to use: find the intersection of your password’s length with its character combination.

So, for example, ‘718462’ can be cracked instantly, as can ‘xgts’.

Note that this chart does not show the effect of dictionary attacks, which are typically tried before the brute-force approach. A dictionary attack tries to guess a password based on a list of common passwords.

If your password is in the red or purple areas, you should really think about making it longer and more complex. Longer, more complicated passwords are also more difficult to remember, especially when you use a different password for every site and service (and you really should), but there’s a simple solution to that: use a password database.

I use both Password Corral, which is a free, standalone Windows program, and 1Password, which is not free, but has some useful features.

Given that most of the web-based password managers have been hacked at one time or another, I still recommend using standalone software if possible.