 boot13
Someone has apparently figured out how to use Microsoft’s search engine to send garbage traffic to targeted web sites. In recent weeks, one of my client sites has been subjected to a steady stream of worthless traffic from a range of IP addresses owned by Microsoft and used by its search crawler, bingbot.
Here’s a request from bingbot that was received at the exact same moment as three similar requests recently:
13.71.172.235 - - [30/Sep/2026:12:17:16 +0000] "GET /catalogsearch/result/index/?caliber=145&dir=asc&order=price&p=2&q=C%3A%5CUsers%5CLENOVO%5CDesktop%5CAll+translations%5C2-+Translations%5CReceipts%2C+Invoices%2C+Bills%2C+etc%5C2023%5C9-+September+till+December+2023%5CReceipt+No.+1836+-++Phoenicia+Station+-+Baabda+-+24+October+2023%5CEnglish+-+Receipt+No.+1836+-++Phoenicia+Station+-+Baabda+-+24+October+2023.pdf HTTP/1.1" 403 494 "-" "Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; bingbot/2.0; +http://www.bing.com/bingbot.htm) Chrome/116.0.1938.76 Safari/537.36"
Astute readers will notice that this request was rejected by the target web site (the HTTP response status code is 403 – Forbidden). That’s because the site is actively blocking all the IP addresses used by bingbot. Well, the ones I know about anyway. You can also see that the host sending the request identifies itself as ‘bingbot/2.0’.
To confirm that these requests are in fact coming from legitimate bingbot hosts, I looked up the source IP address (along with many others), and found that 13.71.172.235 is one IP in the range (CIDR) 13.64.0.0/11, which is owned by Microsoft Corporation. It’s part of a Microsoft Azure Cloud data center in Toronto, Canada, within the Microsoft domain msn.com.
There’s also a tool on the Bing Webmaster Tools site that checks whether an IP address is part of bingbot. I used it to confirm that 13.71.172.235 is indeed bingbot.
The first part of the request is GET /catalogsearch/result/index. This is the type of request that is logged when a (human) user performs a search using the site’s own search function. The other three requests (received at the exact same time) were also search requests, using different search terms.
There are several reasons why these requests make no sense:
- The search terms are unrelated to the subject of the web site being searched.
- A human site user would not (and could not) send multiple search requests at the exact same moment, especially without related requests before and after each search request.
- There is no way that the information returned by the web server in response to these requests is of any use to bingbot or any other search engine.
- The primary function of search bots like bingbot is to collect information from web sites, which is done by reading a site’s home page, making a list of links to other pages on the site found on the home page, then visiting those other pages and processing them the same way. That’s the simplified version of what they do; search bots also read sitemaps to find pages to index. But the requests we’re seeing from bingbot are for pages that do not appear anywhere on the site or in its sitemap.
- Search engines are supposed to read and follow the instructions in the special site file called ‘robots.txt’. For the site in question, there are directives in robots.txt that specifically disallow ‘catalogsearch’ requests by all bots. Bingbot is clearly ignoring those directives.
- In my attempts to mitigate this problem, I added a directive to robots.txt that disallows all access by bingbot. That directive was also ignored by bingbot, which left me with no choice but to block bingbot hosts completely.
- The search request is looking for a PDF file on a specific path. The web site in question does not serve any PDF files, and certainly not from a local Windows folder.
Unfortunately, search requests like the one above tend to use more server resources than ordinary requests, such as a request to view a single product page. When several complex search requests are made at the exact same moment, they can have a significant (negative) effect on site performance. When that happens every few minutes, all day, every day, the cumulative effect can cause the site to become unresponsive. That is the definition of a Denial of Service (DoS) attack. When the requests come from multiple IP addresses, that’s a Distributed Denial of Service (DDoS) attack.
The good news is that since the requests are all coming from bingbot hosts, it’s easy to spot and block them. Many DDoS attacks come from unrelated hosts, and don’t identify themselves as anything other than ordinary web users, which makes them more difficult to categorize and block.
Here’s another one of the four requests received at the same time as the one above:
13.71.172.235 - - [30/Sep/2026:12:17:16 +0000] "GET /catalogsearch/result/index/?action=152&ammotype=194&cat=62&condition=568&q=most+workshop+1+%E0%B8%95%E0%B8%B1%E0%B8%A7%E0%B8%AD%E0%B8%A2%E0%B9%88%E0%B8%B2%E0%B8%87%E0%B8%81%E0%B8%B2%E0%B8%A3%E0%B8%A7%E0%B8%B4%E0%B9%80%E0%B8%84%E0%B8%A3%E0%B8%B2%E0%B8%B0%E0%B8%AB%E0%B9%8C%E0%B9%81%E0%B8%A5%E0%B8%B0%E0%B8%AD%E0%B8%AD%E0%B8%81%E0%B9%81%E0%B8%9A%E0%B8%9A%E0%B8%AD%E0%B8%B2%E0%B8%84%E0%B8%B2%E0%B8%A3%E0%B8%9E%E0%B8%B1%E0%B8%81%E0%B8%AD%E0%B8%B2%E0%B8%A8%E0%B8%B1%E0%B8%A2+5+%E0%B8%8A%E0%B8%B1%E0%B9%89%E0%B8%99&sale_status=1142 HTTP/1.1" 403 494 "-" "Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; bingbot/2.0; +http://www.bing.com/bingbot.htm) Chrome/116.0.1938.76 Safari/537.36"
As you can see, the query text includes a long string of encoded characters. When decoded, the string is “ตัวอย่างการวิเคราะห์และออกแบบอาคารพักอาศัย 5 ชั้น”. Those non-English characters are Thai, and translate to “Example of the analysis and design of a 5-story residential building.” The web site in question is in English only, and the translated search string is completely unrelated to the subject of the site.
Currently, these pointless requests from bingbot hosts comprise about one quarter of all traffic hitting the site. About one request in 20 looks like it might be legitimate bingbot crawling activity. Most are like the ones above.
I did reach out to Microsoft/Bing support about this, but they don’t seem very interested in solving the actual problem, and instead are insisting that I unblock bingbot so that it can read the crawling instructions specific to bingbot in the site’s robots.txt file. They’ve asked me to add a crawl-delay directive to robots.txt, which — if bingbot paid attention to it — should reduce the number of requests coming from bingbot. But even if that worked, it would not address the actual problem.
I can’t justify opening up the site to this traffic just to jump through a pointless hoop. Luckily, very few people actually use Bing search, so blocking bingbot is unlikely to have much effect on the amount of legitimate traffic coming to the site.
In my opinion, there are two possible explanations for this bizarre bingbot traffic. The first is that there are serious bugs in bingbot or in its configuration. That seems unlikely. The second is that someone has found a way to hijack publicly-available tools provided by Microsoft to send the traffic.
The Bing Webmaster Tools page includes a tool for checking a URL. Previously, any URL could be entered. At some point, Microsoft changed this tool so that only URLs for web sites owned by the user can be checked. So it seems unlikely that this is the method being used. Of course it’s also possible that the perpetrators have found a workaround for this limitation.
Only time will tell whether Microsoft will take this problem seriously, determine what flaw is allowing these requests, and fix the flaw. In the meantime, although the requests continue, they are blocked and logged, and have little effect on the site.
Like many people, I was a huge fan of Google when its search service first became available. Before Google, web searching was frustrating and perilous. I’ve gradually become less of a Google fan over the years, but at least their search bots respect robots.txt, and don’t incessantly crawl nonexistent URLs with nonsensical search terms.
 In the never-ending search for content to feed into their Large Language Models, ‘AI’ companies are using distributed networks of bots (automated programs) to download the contents of web sites everywhere on the Internet. Many sites are being overwhelmed by this traffic. Some site owners are being forced to upgrade their hosting service, while others have simply shut down.
 I’ve enjoyed playing around with generative AI tools like ChatGPT and the new, generative features of image editors. I used ChatGPT to generate most of the
 Security professionals have been saying it for years. The specific dangers associated with email have changed during that time, but the advice remains valid, and applies to everyone who uses email.
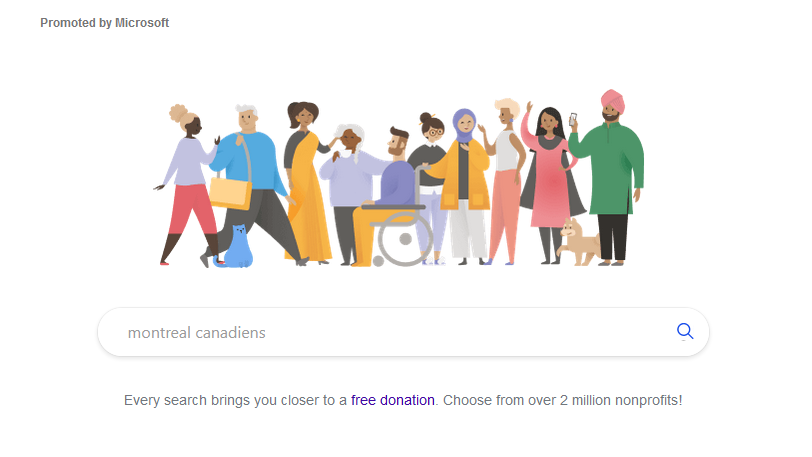
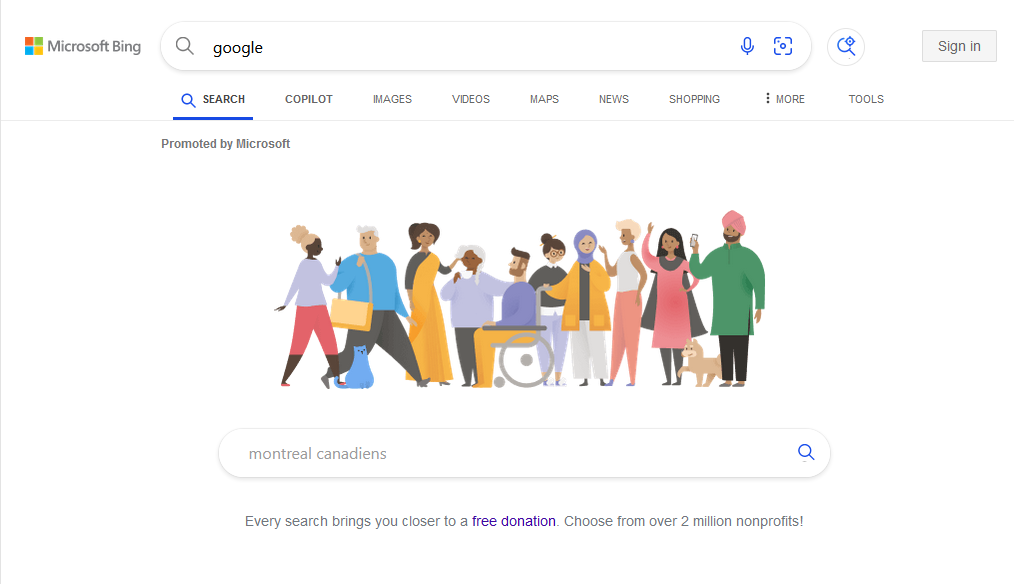
 The folks at Microsoft are once again demonstrating their creativity in thinking up ways to trick people into using its web search service, Bing.
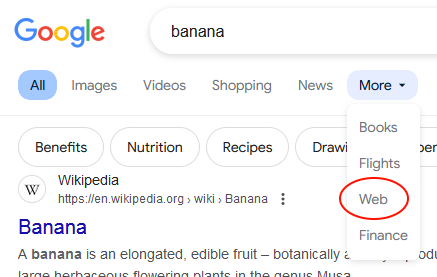
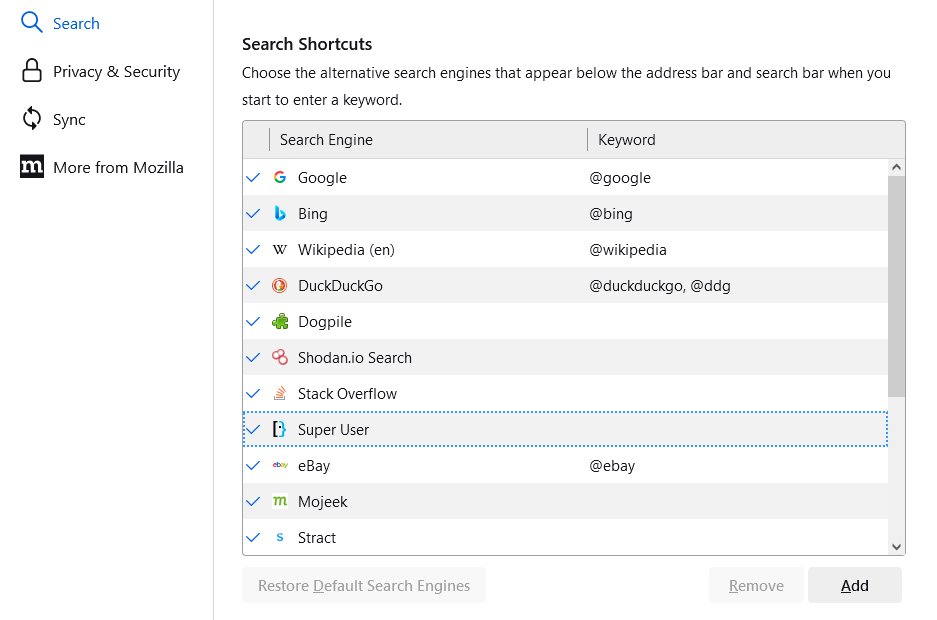
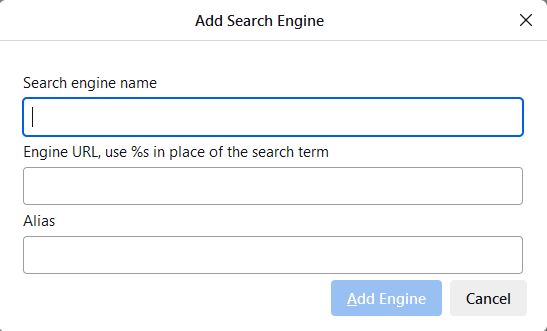 In the small dialog that appears, enter a name for the new search (I call it ‘Google Classic’), the URL